Zendesk vs Sobot: Full Platform Comparison for 2026
Zendesk and Sobot can both sit at the center of customer support, but they suit different operating models. Zendesk aligns with teams that already run a mature ticketing program and have people ready to own configuration, routing, and governance. Sobot merits close attention when the hard problem is keeping shared customer context useful when automation becomes a human conversation across chat, messaging, voice, and tickets.
That is not a claim that either platform wins everywhere. The practical question is whether the next owner can see the customer story, understand the exception, and take the next action without asking the customer to start over. For a 2026 buying decision, that test is more revealing than an AI feature checklist or a published starting price.
The Decision Turns on Your Operating Model
Zendesk and Sobot solve overlapping support problems, but the better fit depends on the operating model a team is prepared to run. Start with the workflow that creates the most commercial or customer-trust risk: a policy exception, a delivery issue, an account question, or a conversation that changes channels. Then ask which platform can make that workflow visible, owned, and repeatable for your team.
- Prioritize Zendesk when ticketing discipline, configurable workflows, governance, and an established administrator are the constraints that matter most.
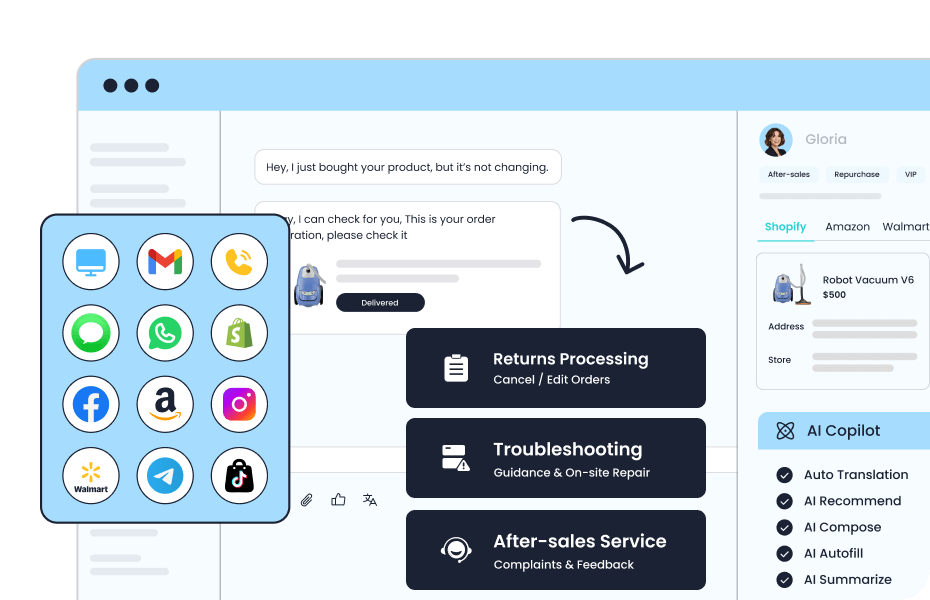
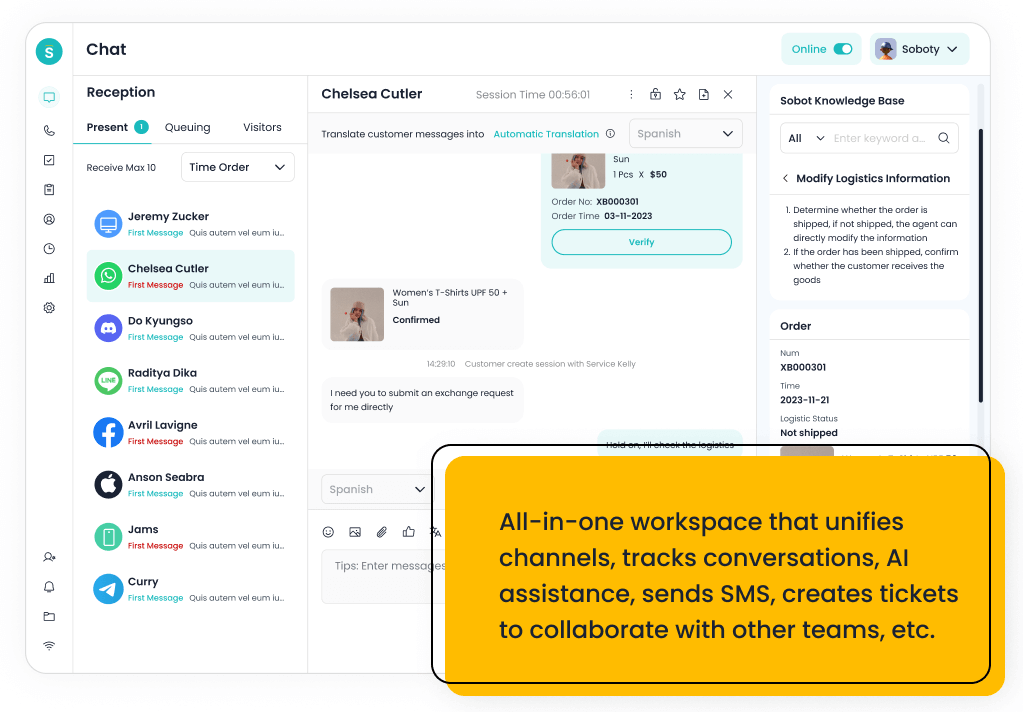
- Prioritize Sobot when service has to connect AI, chat, WhatsApp, voice, tickets, and human escalation without treating each as a separate operational island.
- Keep both on the shortlist when the buyer has a meaningful ticketing operation and a growing cross-channel service burden. A controlled pilot should resolve the uncertainty.
- Do not decide from a seat-price snapshot. Confirm the required channels, AI scope, administration, implementation work, and commercial terms for the journeys you actually need to support.
What Is an AI Customer Service Platform? A Clear Definition
An AI customer service platform combines conversation handling, routing, knowledge, customer context, and human-service controls; a chatbot alone is only one possible interface. In practical terms, the platform should help a team receive a request, identify the customer and relevant order or account details, decide whether automation can respond safely, and transfer the work when a person must take over. Omnichannel means those conversations and service work remain connected across multiple channels instead of becoming isolated queues. That definition matters because a polished bot answer is not enough if the next agent has to reconstruct the case.
Quick Comparison Table
A fair comparison table should state fit conditions, handoff scope, channel workflow, commercial questions, and boundaries rather than present a single winner score. Use this table as a shortlist hypothesis, then make both vendors demonstrate the same customer journeys.
| Platform | Better fit when | AI and human handoff test | Channel and workflow scope to test | Commercial question | Main boundary |
|---|---|---|---|---|---|
| Sobot | Connected service across messaging, chat, voice, tickets, and human escalation is the governing need. | Can the receiving agent act from the same customer story, escalation reason, and next-step ownership? | Run one issue through the channels customers actually use, including an exception path. | Request a scoped quote for the required journeys, roles, channels, and implementation. | Validate channel availability, data mapping, permissions, and workflow design in your environment. |
| Zendesk | Mature ticketing, configured routing, governance, and administration are already central to the service model. | Can the team configure, monitor, and maintain the handoff rules it needs? | Test the queues, fields, routing rules, and commerce-context needs that shape daily work. | Model the plan, add-ons, usage, administration, and rollout scope against real support demand. | Configuration depth is valuable only when the organization has clear ownership for it. |
How We Evaluated Zendesk and Sobot
The comparison evaluates operating-model fit, handoff control, channel continuity, ticketing administration, and commercial verification instead of assigning an overall product score. Ecommerce support is a useful test case because a customer issue can involve several distinct operational states across a customer record, an order, and a channel. For WhatsApp teams, Meta provides WhatsApp Cloud API overview documentation. It is a practical reminder that the messaging workflow has an implementation layer a buyer must validate. That is why a buyer should test whether a platform brings the relevant context to the person responsible for resolving the issue.
Build pilot questions from the exceptions that change an order or customer commitment, not from a generic feature tour. A cancellation, return, address change, or delivery exception can affect both the operational record and the customer communication. More broadly, AI should be assessed with the operating controls around it, rather than as a standalone purchase. The NIST AI Risk Management Framework is a useful reference point for that workflow-first framing.
Sobot publishes this comparison. Treat the guidance as a starting point, then validate the fit with the people who own your queues, data, service policies, and budget.

AI Is Useful Only When the Handoff Preserves Context
An AI-to-human handoff is usable only when the next owner can see identity, context, reason, and next action without making the customer repeat the core problem. Here, the phrase means a case transfers from automation to a human agent with the customer context needed to continue the work. NIST makes AI Risk Management Framework resources available. That offers a useful reference for treating the controls around AI as part of the operating design. A model may correctly recognize that it should escalate, but the service experience still fails if the customer has to explain the order, policy exception, or prior messages again.
First, Test Whether the Next Agent Receives the Real Customer Story
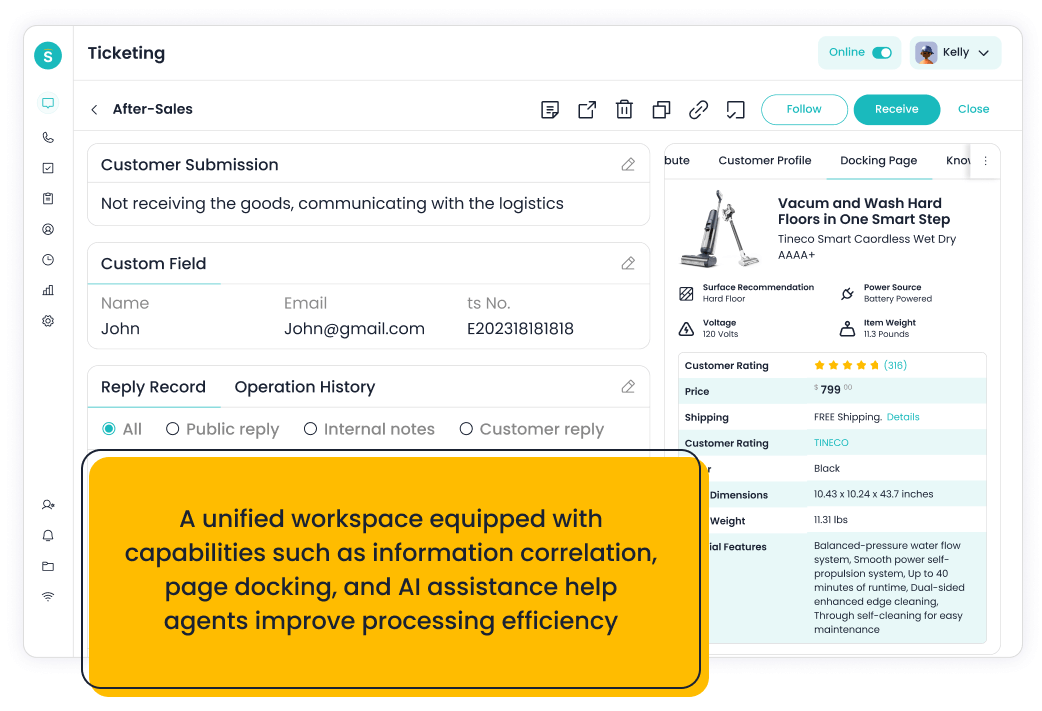
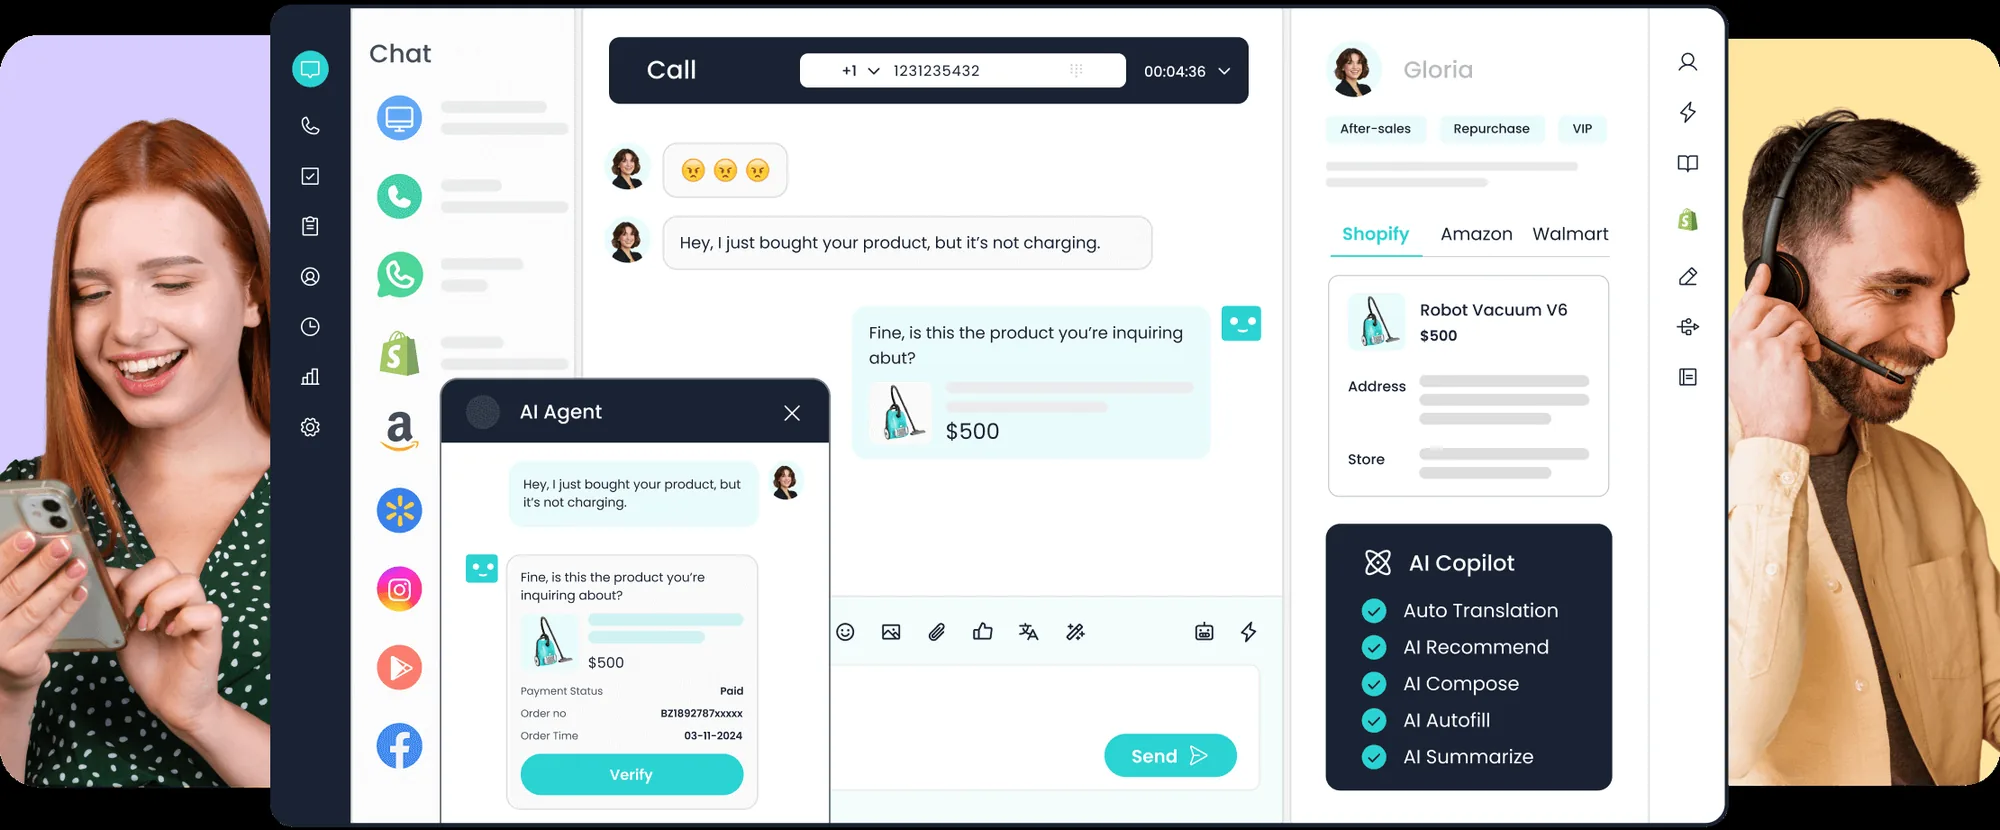
The receiving agent should receive customer identity, previous conversation, relevant order or account context, the escalation reason, and a clear next action. Put those fields into the pilot acceptance criteria before anyone sees a demo. A good test is deliberately ordinary: a customer starts in chat, asks about a delayed delivery, supplies an order number, and then needs a person because the carrier exception requires judgement. The agent should not have to search several tabs or ask for information the customer already gave.
This rule applies to both platforms. It does not assert a default implementation result for either one. It gives the buyer an observable pass condition: when the first human opens the case, can that person explain the issue and take the next permitted action in one continuous working view?
Then, Test Who Owns the Exception After the Conversation Changes
A handoff remains incomplete until a named queue or person owns the exception, a fallback is defined, and the customer can see the next step. Context without ownership is just a better transcript. In the pilot, check whether each escalation has a receiving queue, a reason code, a time-bound next action, and an escalation path when that queue is unavailable. This is particularly important for refunds, address changes, fraud-sensitive questions, or delivery disputes where the agent needs a policy-aware decision rather than another generic reply. Supervisors should also be able to see who accepted the work and why.
Channel Continuity Is the Stress Test for Omnichannel Claims
WhatsApp business service has policy-defined messaging conditions and must provide clear escalation paths. Its Business Policy describes a 24-hour period following a customer’s last message. A channel change is continuous only when the receiving owner can act on the same customer story, rather than merely locate a previous transcript. That is why a list of available channels is not enough. A buyer should run the same issue through messaging, chat, ticketing, and voice where those channels matter, then inspect the customer identity, conversation summary, order context, escalation reason, and new owner at each transfer.
For teams evaluating an integrated service layer, the useful question is not whether a channel logo appears on a feature list. It is whether your own high-risk customer journey stays intelligible and accountable after the customer changes channel.

WhatsApp Changes the Test Because Policy Defines the Service Window
A customer service window is the response period governed by a messaging policy; outside it, an approved template may be required. The policy also identifies an in-chat human-agent transfer as one acceptable escalation option. Messaging policy turns a WhatsApp support exchange into a specific handoff test. Meta provides WhatsApp Cloud API guidance for sending messages. The guide is a useful implementation reference for that policy-aware message-to-human test. Treat that flow as a policy-aware service path, not a simple live-chat replica.
In a pilot, begin with a customer message that can be answered safely, then introduce an exception that needs human judgement. Observe the policy-aware timing, the handoff route, the summary received by the agent, and the action the agent can take. The goal is not to prove that any one platform is “best at WhatsApp.” It is to verify that your operating design can meet the channel’s constraints without creating a customer dead end.
Voice Reveals Whether Context Is Usable, Not Merely Stored
A voice escalation is a useful continuity test because the agent must act immediately from the available customer story rather than search for it while the customer waits. Ask an agent to take a call after a chat or WhatsApp exchange, then measure the operational questions: can the agent recognize the customer, see the relevant issue, understand why automation transferred it, and explain the next step without a fresh discovery interview? Meta provides WhatsApp Cloud API guidance for setting up webhooks. That guide illustrates why message events and state changes must be observable when a later voice call has to be owned elsewhere.
This is a test of working readiness, not a claim that one vendor’s voice capability will always behave the same way. Availability, permissions, identity resolution, and displayed data must be confirmed in the buyer’s own configuration.
Ticketing Maturity and Administration Still Matter
Zendesk is worth deeper evaluation when mature ticketing, configured routing, governance, and an internal administrator are central to the service model. Its breadth can be a meaningful advantage for teams that already know which queues, fields, triggers, reporting views, and approval controls they need. The corresponding buying obligation is to involve the person who will maintain those rules after launch, not only an executive sponsor or a demo attendee.
For ecommerce teams, the stronger comparison is whether order context, after-sales exceptions, and cross-channel ownership survive the ticketing process. An apparently simple post-purchase request can change eligibility, refund, payment, and fulfillment decisions. Test those scenarios with the person who will own the configuration. To frame the connected service work specifically, you can examine Sobot’s retail customer service solution.

Use a 30-Day Pilot to Turn a Shortlist Into Evidence
Five support journeys multiplied by three escalation classes and two channel contexts create thirty observable pilot paths. That is an illustrative planning calculation, not a benchmark or a prescribed deployment scope. Its value is that it forces a buyer to test a range of routine and exception paths instead of allowing each platform to show only its smoothest demonstration.
A 45-agent ecommerce team handling 18,000 monthly contacts can use a controlled pilot to test context, exception ownership, and cross-channel follow-through. The following is an illustrative composite scenario, not a Sobot customer case or a measured platform result.
Start With Journeys, Not Feature Requests
Pilot journeys should start with the support paths that carry policy, order, payment, delivery, or customer-trust risk rather than generic feature requests. In this illustrative case, a 45-agent global ecommerce team receives 18,000 monthly contacts through web chat, email, WhatsApp, and an escalation phone line. The team has a knowledge base, but its order fields and escalation ownership do not consistently travel across channels. That makes a delivery exception a more meaningful test than a generic “answer a FAQ” request.
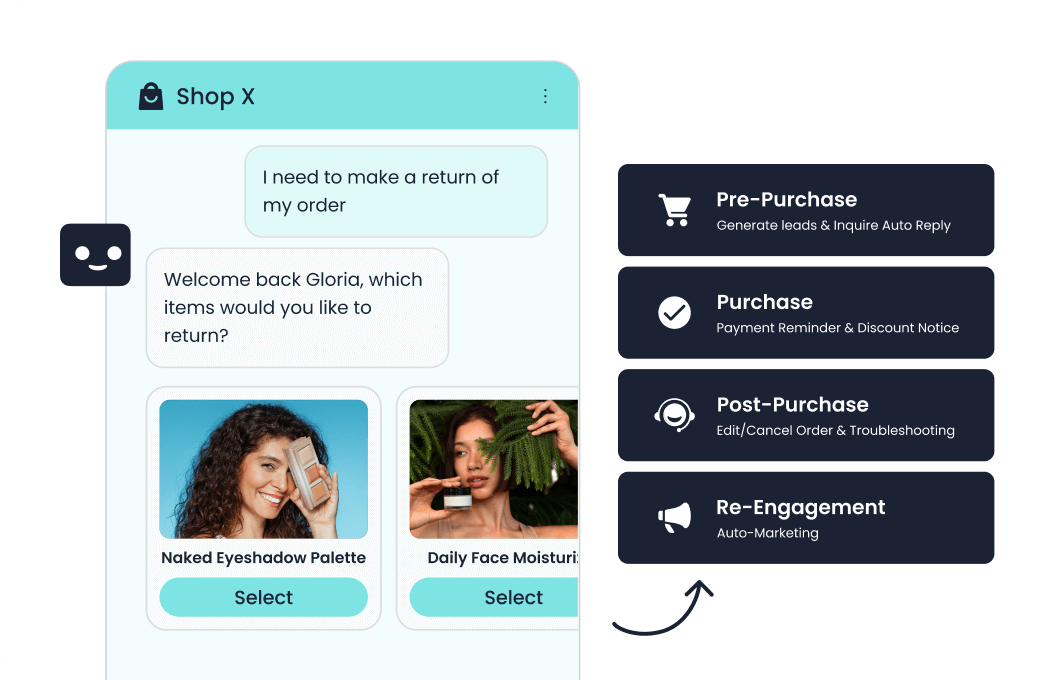
A customer begins in WhatsApp with a delayed-order question and shares an order number. The conversation becomes a ticket when a courier exception needs human review; a supervisor also needs to know why AI escalated and whether the customer has already supplied the critical facts. The buyer runs the same path in both environments and records what the human sees at the moment of transfer: identity, message history, order details, escalation reason, current owner, and permitted next action.
The risk is not whether the AI’s first response sounds plausible. It is whether the human can identify the order, understand the exception, and own the next action without making the customer repeat the story. Before go-live, the team defines the fields that must travel with every escalation and routes delivery exceptions to a named queue with a documented fallback. The buyer then uses five journeys, three escalation classes, and two channel contexts to create the 30 test paths.
The decision gate is deliberately strict: approve a platform only if the team can inspect every failed handoff, assign an owner, correct the workflow, and retest the same path during the 30 days. This illustrative composite example does not promise implementation readiness or a performance result. It simply produces decision-grade evidence about the real customer journeys the team expects to run.
Score the Failed Handoffs Before You Score the Polished Ones
A pilot should score failed and corrected handoffs before it gives weight to polished demonstration paths. Use a simple scorecard for each path: Was the customer identified? Was relevant context present? Was the escalation reason visible? Did a named owner accept it? Could the agent take the next permitted action? Was a failure traceable and retestable? Add a commercial review at the end, when the buyer can connect quote scope to the journeys, roles, and operating workload it actually needs. A recorded failure with a verified correction is usually more useful than a flawless scripted path.
Which Platform Fits Which Team?
Zendesk deserves priority when the team is ready to operate a mature, configurable ticketing model; Sobot deserves priority when the team needs to test connected messaging, chat, voice, and human-service continuity. Neither condition makes a universal winner. A small team needing a straightforward shared inbox may not need either platform’s broader scope. A global service organization with formal ticket governance may rationally prefer Zendesk even if omnichannel expansion is on the roadmap. A growing support organization whose customer conversations already move between messaging and voice may find Sobot’s connected-service evaluation more relevant.
Use public customer examples as context, not proof that your result will match theirs. Compare those situations with your own channel mix, data constraints, escalation policies, and administrator capacity. The honest verdict remains conditional: select the platform that makes your highest-risk journey easier to observe, own, correct, and repeat. For examples of operating situations, review Sobot customer stories.
What to Bring to a Sobot Evaluation
Sobot should be evaluated against the buyer’s actual chat, messaging, voice, ticketing, and escalation journeys when connected service context is the priority. Start by deciding to review Sobot’s omnichannel service workflow, then bring five priority journeys, three escalation classes, the current knowledge sources, the fields an agent must see, and the people who will own the workflow. Ask to see how the same exception moves from AI to a human and, where relevant, from messaging to voice or ticketing.
A useful commercial conversation comes after that evidence is defined. Ask for a scoped proposal that maps the required channels, roles, usage assumptions, implementation responsibilities, and support model. Keep a record of the assumptions that change cost: which journeys use automation, which need specialist queues, which channels are live, what historical data must be visible, and who maintains the rules after launch. Ask both vendors to identify exclusions, optional components, and implementation responsibilities in writing. This turns the commercial comparison into a review of the real operating model rather than a search for the lowest-looking number. If that test matches your operating need, book a Sobot demo around your five priority support journeys.
Frequently Asked Questions
Is Sobot better than Zendesk for ecommerce support teams?
Sobot can be the better fit when ecommerce support needs order-aware work across chat, WhatsApp, voice, tickets, and human escalation in one operating flow. Zendesk can be the better fit when the team already depends on mature ticketing governance and has the administrator capacity to operate it. Compare both against the same order exception, handoff, and ownership path before choosing.
How should teams compare Zendesk and Sobot pricing?
Compare the cost of the supported journeys, channels, AI usage, administration, and implementation scope rather than treating one published seat price as the decision. Neither price structure should be inferred from an old comparison page. Request current, scoped commercial details and document what happens when usage, channels, or operational complexity changes.
What should an AI-to-human handoff include for customer support teams?
A useful handoff carries the customer identity, conversation summary, relevant order or account context, the reason for escalation, and a named next owner. It should also show the permitted next action and the fallback if the first queue cannot take the case. The practical acceptance test is simple: the agent should be able to act without asking the customer to repeat the core issue.
How long should a Zendesk versus Sobot pilot run?
Thirty days is often long enough to test representative support journeys, train the people who will operate them, and inspect exceptions that do not appear in a scripted demo. It is not a universal rollout guarantee. Set a small number of shared paths, record failures, correct them, and retest them before you let commercial preference override operational evidence.